Video - Video & Streaming
Cloudflare Stream Pricing 2026: Live, VOD and Storage Costs Explained
Cloudflare Stream Pricing 2026: Live, VOD & Cost Playbook One number decides whether Cloudflare Stream pricing ...
A working cdn log delivery pipeline takes about 40 minutes to stand up on an existing object storage bucket plus one collector host. The end state: edge access logs landing in hourly partitions, a normalized cache-status field, and a cache hit ratio that reconciles with your CDN's own dashboard within 2%. Two delivery modes exist and they are not interchangeable. Real-time streaming puts lines in front of a query engine in 5–60 seconds; batch push writes compressed files every 5–15 minutes, sometimes hourly. Most teams need both, routed into one store.
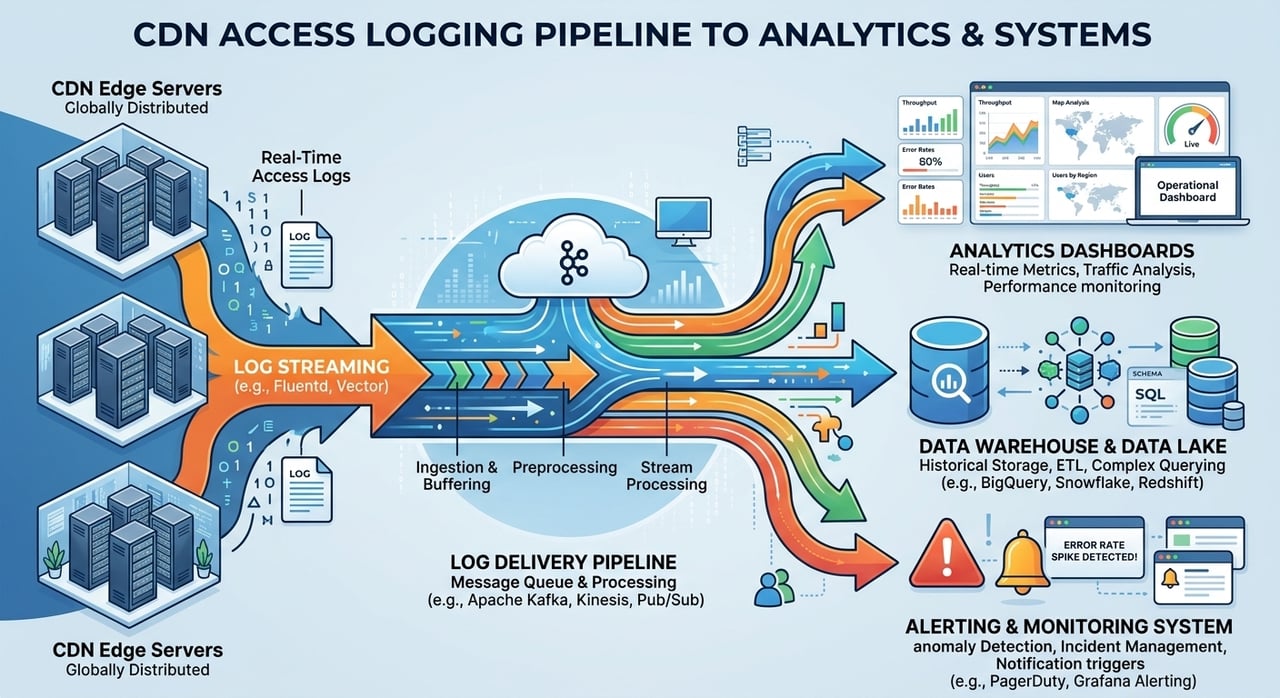
Every edge node writes a line per request into a local buffer. From there the CDN either ships the buffer over a persistent connection to a customer endpoint or message bus (streaming), or rolls it into a compressed object and writes it to your bucket on a time or size trigger (batch push). Both are at-least-once. Neither is ordered.
The field set is usually configurable, and that choice is permanent for historical data. Fields you do not enable today cannot be backfilled tomorrow.
| Dimension | Real-time streaming | Batch push |
|---|---|---|
| Time to queryable | 5–60 seconds | 5–15 min typical, up to 60 min |
| Duplicates | Expected on retry, 0.1–1% typical | File-level, dedupe by object key |
| Behavior when consumer stalls | Permanent gap past buffer window | Retries, late files arrive out of order |
| Cost driver | Always-on consumers, per-GB ingest | Object writes plus storage |
| Best for | Incident triage, abuse detection, live error budgets | Billing reconciliation, cache tuning, BI |
Use streaming for decisions measured in seconds and batch push for anything you would happily re-run a week later.
Enable batch push first. It is the cheaper baseline and it is the source of truth for reconciliation. Add streaming only for the subset of traffic where a 10-minute delay changes an action.
A delivery tier averaging 1,000 requests per second produces roughly 3.6 million log lines per hour. At about 450 bytes per line in an extended W3C-style access format, that is near 1.6 GB per hour uncompressed, or about 160 MB per hour with zstd compression at level 3 in 2026 measurements. Over 30 days: roughly 1.15 TB raw, 115 GB stored.
Write the schema down as a file in your repo. Rename vendor fields to your own names at ingest, so a future CDN swap changes one transform instead of every dashboard.
schema_version: 1
fields:
  - timestamp_ms        # event time at the edge, UTC epoch millis
  - request_id          # vendor request identifier, used for dedupe
  - client_ip           # from the CDN field, never the socket peer
  - host
  - path                # query string stripped at ingest
  - method
  - status
  - bytes_sent
  - cache_status        # raw vendor value, normalized downstream
  - ttfb_ms             # edge time to first byte
  - origin_time_ms      # present only on misses
  - protocol            # h2, h3, http1.1
  - tls_version
  - user_agent
  - country
  - pop_region          # coarse geography bucket, not node identity
Cache status vocabularies differ across vendors: hit, HIT, cached, hit-stale, revalidated. Collapse them into a boolean plus a reason code once, at ingest. Do not push that logic into dashboards, where it will drift.
sources:
  cdn_stream:
    type: http_server
    address: 0.0.0.0:8080
    decoding:
      codec: json

transforms:
  normalize:
    type: remap
    inputs: [cdn_stream]
    source: |
      .cache = downcase(string!(.cache_status))
      .is_hit = includes(["hit", "cached", "hit_refresh", "revalidated"], .cache)
      .tenant = split(string!(.host), ".")[0]
      .path = split(string!(.path), "?")[0]
      del(.user_agent_raw)

sinks:
  lake:
    type: aws_s3
    inputs: [normalize]
    bucket: LOGS_BUCKET_NAME        # substitute your bucket name
    key_prefix: "cdn/dt=%Y-%m-%d/hr=%H/"
    compression: zstd
    encoding:
      codec: json
    batch:
      max_bytes: 268435456
      timeout_secs: 300
    buffer:
      type: disk
      max_size: 21474836480
Partition by event time, not arrival time. Late files are normal in batch push, and arrival-time partitioning silently smears an outage across two hours. Compact small objects into 256 MB columnar files once per hour; query cost on a well-compacted hour is typically 5–10x lower than on raw JSON.
pipeline:
  partition_keys: [dt, hr, tenant]
  partition_time_source: event_time
  compaction:
    format: parquet
    target_file_bytes: 268435456
    sort_keys: [tenant, timestamp_ms]
  retention:
    hot_days: 30
    cold_days: 400
alerts:
  delivery_lag_seconds:
    stream_warn: 90
    stream_page: 600
    batch_warn: 1200
  hourly_line_count_drop_pct: 20
  duplicate_request_id_pct: 1.0
Disable the sink in the CDN console. That single toggle stops the write path; the collector drains its disk buffer within minutes. Apply a one-day expiry lifecycle rule to the test prefix rather than deleting objects by hand, so in-flight writes do not error. Keep the schema file. One honest caveat: while streaming is off, those lines are gone permanently, and most batch push implementations backfill a limited window or nothing at all.
| Symptom | Cause | Fix |
|---|---|---|
| Pipeline hit ratio 8–12 points below the CDN dashboard | Dashboard measures bytes, pipeline measures requests | Compute both ratios and label them separately |
| Hourly partition sizes swing 5x | Partitioned on arrival time, late files land in the wrong hour | Partition on event time, recompact affected hours |
| 2–5% of lines missing during a traffic spike | Collector memory buffer overflowed | Switch to disk buffer, size it for 30 minutes of peak |
| Every client IP identical | Logging the socket peer behind a proxy hop | Use the CDN's client IP field explicitly |
| Files stop arriving after a config change | Rotated credential or altered prefix permission | Alert on delivery lag, not on error rate, which reads zero when nothing arrives |
Silence is the dangerous failure mode: a pipeline receiving nothing reports perfect health unless you alert on delivery lag and hourly line counts.
Sample asymmetrically. Keep 100% of non-2xx responses and 1–10% of successful static asset hits; on a large software delivery workload this cuts volume by 70–90% while preserving every diagnostic signal. Strip query strings at ingest unless you have a specific attribution need, since unbounded path cardinality dominates columnar storage cost.
Vendor behavior differs in ways worth checking during selection: which fields are exposed, whether both delivery modes exist, and how quickly the schema can be changed. BlazingCDN handles log delivery configuration per account with roughly one-hour onboarding, which matters when your schema decision needs to be made before launch rather than after. Review the available CDN delivery and configuration features against the field list in Step 2 before you commit.
Trade-off worth naming: this pipeline tells you what the edge saw, not what the browser experienced. Edge time to first byte excludes last-mile latency and render time. Pair it with client-side timing data, or you will optimize a number your users never feel.
Real-time CDN logs stream individual request records to an endpoint within 5–60 seconds of the request, while batch push writes compressed files to object storage every 5–15 minutes. Streaming supports live triage and abuse detection. Batch push is cheaper, more durable under consumer failure, and remains the correct source for billing reconciliation.
Budget roughly 450 bytes per uncompressed log line and a 10:1 compression ratio with zstd. At 1,000 requests per second that is about 1.15 TB raw and 115 GB stored per 30 days. Sampling successful static responses at 10% typically reduces stored volume by 70–90% without losing error visibility.
No. CDN log delivery records what the edge served, including cache status, status codes, and edge time to first byte, but it cannot observe last-mile latency, connection setup on the client, or rendering. Use logs for delivery-side truth and client instrumentation for experience metrics, then join them on a shared request identifier.
Mismatches usually come from three sources: at-least-once duplicates inflating counts by 0.1–1%, time zone or arrival-time partitioning shifting requests between hours, and dashboards that measure bytes where the pipeline measures requests. Reconcile on a closed UTC hour, dedupe by request identifier, and compare like units.
Pick one closed UTC hour from yesterday. Count lines in your partition, count distinct request identifiers, and compare both against the request count your CDN reports for that same hour. If the gap exceeds 2%, you have either a dedupe problem or a partitioning problem, and the distinct-count delta tells you which. Then instrument delivery lag as p99 of processing time minus event time and alert on it. That one metric catches the failure mode that every other alert misses: logs that simply stopped arriving.
Video - Video & Streaming
Cloudflare Stream Pricing 2026: Live, VOD & Cost Playbook One number decides whether Cloudflare Stream pricing ...

Learn
Picture this: a world where the speed of your website can make or break your business. In an age where digital ...